The best web scraping tools in 2026 depend on the job: Scrapy or Crawlee if you have developers, Playwright for JavaScript-heavy sites, Firecrawl for clean data for an LLM app, a scraping API like ScrapingBee or Zyte API if you don't want to run proxies, and Browse AI or Octoparse if nobody on the team codes.
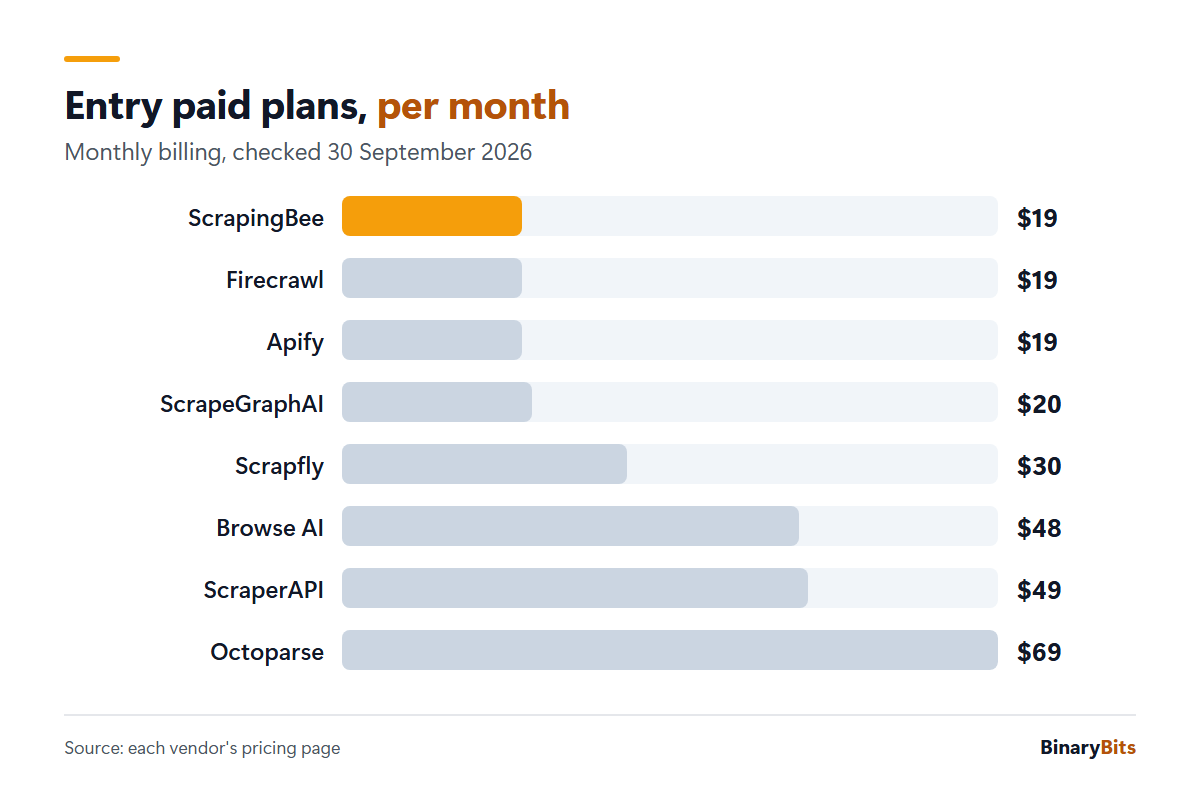
Paid plans start around $19 a month. The bigger cost is the one vendor lists leave out: who fixes the scraper when a site changes. We build scraping pipelines for a living and don't sell any of these tools, so this list is ranked by job, price and upkeep, not by who wrote it.
💡 What you'll get from this post: 12 tools grouped by what they're good at, 2026 prices checked on each vendor's pricing page, and the signs that a tool has stopped being enough.
TL;DR
- Developers: Scrapy (Python) or Crawlee (Node.js and Python), plus Playwright for pages that need a browser. Free, but you run everything.
- LLM apps: Firecrawl or ScrapeGraphAI return clean markdown or JSON without you writing selectors.
- No proxies to run: ScrapingBee, ScraperAPI, Zyte API or Scrapfly. At 100,000 browser-rendered pages a month, expect roughly $83–$149 on list prices, more for hard sites.
- No developers: Browse AI or Octoparse, with scheduling and change alerts on paid plans.
- Pricing pages and change alerts: Visualping or Browse AI monitors for a few pages; a custom pipeline (your own system that collects, checks and delivers the data) once you're tracking thousands of products.
What are the best web scraping tools in 2026?
Here are the 12 we'd shortlist, grouped by the kind of team that gets the most from each. Prices are the entry paid plan on monthly billing, checked on 30 September 2026. "Who maintains it" is the column that decides your real cost.
| Tool | Type | Best for | Entry price | Who maintains the scraper |
|---|---|---|---|---|
| Scrapy | Open-source Python framework | Large crawls by a Python team | Free | You |
| Crawlee | Open-source library (Node.js, Python) | JavaScript teams, mixed HTTP and browser crawls | Free | You |
| Playwright / Puppeteer | Browser automation | Sites that only render in a browser, multi-step flows | Free | You |
| Firecrawl | AI scraping API | Clean markdown for LLM and RAG apps | $19/mo | Vendor, you check output |
| ScrapeGraphAI | AI extraction API + library | Describing fields in plain English | $20/mo | Vendor, you check output |
| Browse AI | No-code, AI-assisted | Monitoring a few sites without code | $48/mo | Vendor, you retrain robots |
| Octoparse | No-code desktop + cloud | Point-and-click extraction on a schedule | $69/mo | You, through the visual editor |
| Apify | Scraping platform + marketplace | Ready-made scrapers, or hosting your own | $19/mo | Actor author or you |
| ScrapingBee | Scraping API | Rendering and proxies behind one API call | $19/mo | Vendor fetches, you parse |
| ScraperAPI | Scraping API | Simple API, billed only on successful requests | $49/mo | Vendor fetches, you parse |
| Zyte API | Scraping API, pay per request | High volume, priced by how hard each site is | Pay as you go | Vendor fetches, you parse |
| Scrapfly | Scraping API | Large credit bundles for high volume | $30/mo | Vendor fetches, you parse |
Which open-source web scraping tools should developers use?
If you have developers and want full control, start with a free framework. You pay nothing for the software and everything for the servers, proxies (other IP addresses to send requests through) and upkeep.
Is Scrapy still the best Python scraping framework?
For large crawls, yes. Scrapy handles queues, retries, throttling and exports out of the box, and it's what we reach for first on Python projects. It doesn't run JavaScript by itself, so pages that only load their content in a browser need Playwright alongside it.
What does Crawlee add for Node.js and Python teams?
Crawlee, from the Apify team, gives you one interface for plain HTTP crawling and browser crawling with Playwright or Puppeteer, plus request queues and session handling. It started in Node.js and now has a Python version. Pick it if your team writes JavaScript or wants to move a crawler onto Apify later.
Playwright or Puppeteer: when do you need a real browser?
You need a browser when the data only appears after JavaScript runs, or when you have to click, scroll or fill a form to reach it. Playwright supports Chromium, Firefox and WebKit from Python, Node.js, Java and .NET. Puppeteer is Node.js only and built around Chrome. Browsers cost far more memory and time per page than HTTP requests, so use them only for pages that need them.
What are the best AI web scraping tools in 2026?
AI scraping tools read the page with a language model instead of fixed selectors (the rules that tell a scraper "the price is in this box"). That's why they suit teams asking the question we see in our search data: how do we get clean, formatted data into our LLM application without maintaining our own crawling infrastructure?
Firecrawl: clean markdown for LLM apps
Firecrawl turns a URL or a whole site into markdown or structured JSON ready for a RAG system (one that looks up your documents before it answers). Its pricing starts with 1,000 free credits, then $19 a month for 5,000 credits, or $83 a month billed annually for 100,000. A basic page costs about one credit.
ScrapeGraphAI: describe the fields, skip the selectors
You tell ScrapeGraphAI what you want in plain English ("product name, price, stock status") and it returns JSON. The hosted API starts at $20 a month for 10,000 credits, and there's an open-source Python library if you'd rather run it yourself.
What's the catch with AI extraction?
- It can be confidently wrong. A model may fill a field with the nearest plausible number. Validate every record against a schema (the list of fields and formats you expect) and simple sanity rules.
- It costs more per page than a parser once your volume is high and the layout is stable.
- It still has to fetch the page. A site that blocks or rate-limits you blocks the AI tool too.
Which web scraping APIs handle proxies, rendering and blocking for you?
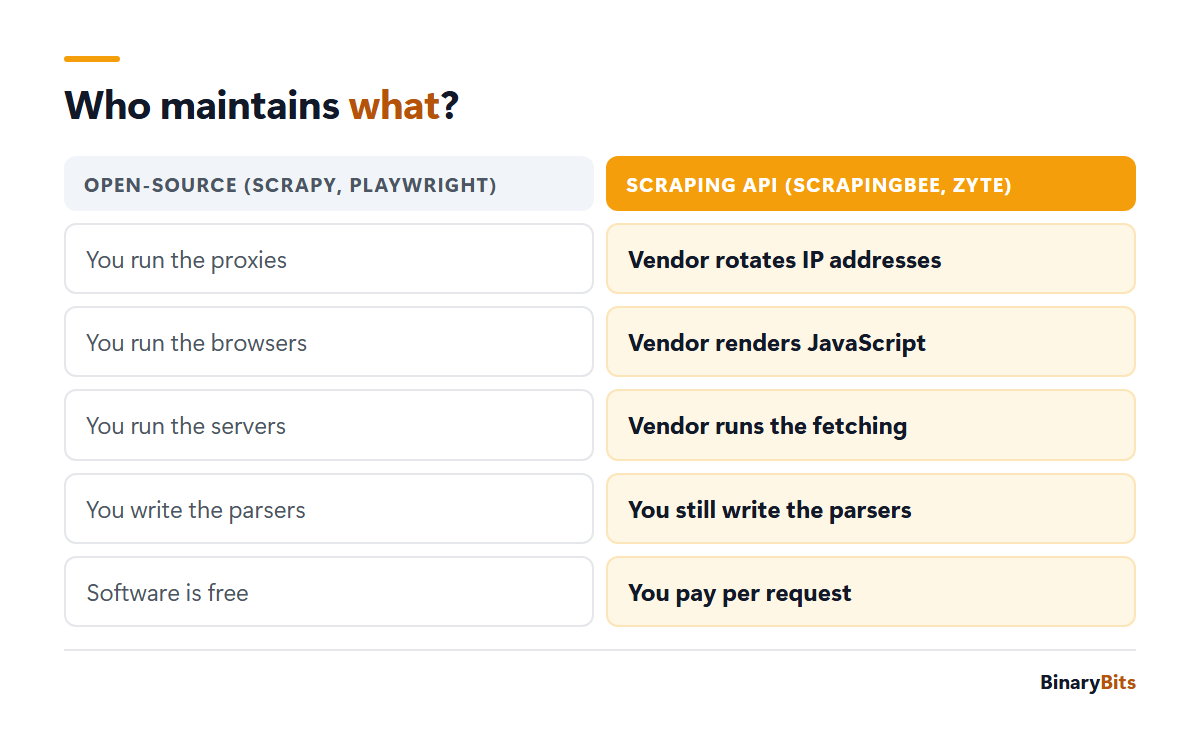
Scraping APIs fetch the page for you: they rotate IP addresses, render JavaScript in their own browsers and retry failed requests. That's what "built-in anti-bot protection" means on their sales pages. You send a URL and get HTML or JSON back, and you still write the code that pulls out the fields.
- ScrapingBee: $19 to $599 a month for 75,000 to 8,000,000 credits. A JavaScript-rendered page costs 5 credits, or 25 with premium proxies (documentation). It also runs scripted clicks and scrolls inside its browser.
- ScraperAPI: 1 credit for a plain request, 10 with rendering, 25 with rendering and premium proxies, and only successful requests are billed. Plans start at $49 a month for 100,000 credits (Capterra).
- Zyte API: pay per request, priced by how hard each site is. List prices run $0.13 to $1.27 per 1,000 plain requests and $1.01 to $16.08 per 1,000 browser-rendered ones, lower with a monthly commitment.
- Scrapfly: $30 a month for 200,000 credits up to $500 for 5,500,000. Credits per request depend on the features you switch on.
- Apify: not one API but a platform. $19 a month buys $19 of usage for running ready-made scrapers ("Actors") or your own code.
⚠️ Note: A tool that can fetch a page doesn't make collecting it allowed. Respect robots.txt, a site's terms and its rate limits, use an official API where one exists, and don't collect anything behind a login. This is general information, not legal advice.
Web scraping API pricing comparison for high-volume users
Entry prices don't tell you much at volume, because each API charges a different number of credits per page. So we worked out the cheapest plan that covers 100,000 browser-rendered pages a month. This is our own arithmetic from the list prices above, checked on 30 September 2026.
| API | Credits per rendered page | Cheapest plan that covers 100,000 pages | Roughly per 1,000 pages |
|---|---|---|---|
| Firecrawl | ~1 | $83/mo (annual billing), 100,000 credits | $0.83 |
| ScrapingBee | 5 | $99/mo, 1,000,000 credits | $0.99 |
| ScraperAPI | 10 | $149/mo, 1,000,000 credits | $1.49 |
| Zyte API | Priced per request | $101–$1,608 pay as you go | $1.01–$16.08 |
| Scrapfly, Apify | Depends on features or the Actor | Test on your own sites | Varies |
Two things move these numbers more than the plan does. Hard sites that need premium proxies cost 25 credits a page on both ScrapingBee and ScraperAPI, five times the base rendered price. And pages that don't need a browser are far cheaper everywhere: always test whether plain HTTP works before paying for rendering.
Which scraping API requires the least maintenance over time?
AI extraction APIs like Firecrawl and ScrapeGraphAI need the least upkeep, because there are no selectors to break when a site changes its layout. Standard scraping APIs remove the work of running proxies (other IP addresses your requests go out through) and browsers, but leave you maintaining parsers.
Either way, something has to notice when the data goes wrong. The maintenance that actually eats time is the silent failure: the scraper returns 200 OK, the file fills up, and half the prices are blank. Why your web scraper keeps breaking covers the usual causes.
Which tools detect and scrape pricing pages automatically?
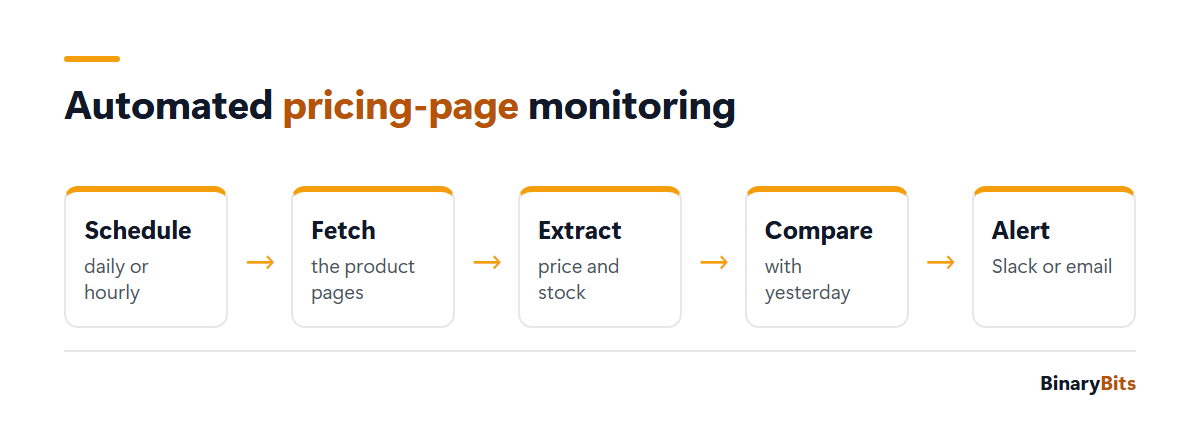
For a handful of pages, a change-detection tool is enough. For thousands of products across many sites, you want a scraper that extracts each price as a field, compares it with yesterday's and alerts you on the difference.
Which scraping tools have built-in scheduling and alerts?
- Visualping: watches a page and alerts on visual, text or element changes. Free for 5 pages checked hourly, $14 a month for 10 pages every 15 minutes, Slack and Teams alerts from the $140 Business plan.
- Browse AI: monitors turn a trained robot into a scheduled check. Hourly on the free plan, every 5 minutes on paid plans from $48 a month ($19 on annual billing).
- Octoparse: scheduling and cloud runs come with the $69-a-month Standard plan. The free plan runs only on your own computer.
- Apify: any Actor can run on a schedule, with webhooks when a run finishes.
When does price monitoring need its own pipeline?
Once you're matching the same product across many sellers, tracking stock as well as price, or feeding a repricing system. Across our projects, one price-intelligence system we built monitors 60,000+ products a day by SKU and sends Slack and email alerts when a price or stock status changes. That's a pipeline, not a tool setting. The e-commerce price intelligence case study shows how it fits together.
Which no-code web scraping tools work for non-developers?
Browse AI and Octoparse are the two we'd give a non-technical team. Both let you click on the data you want, and both run on a schedule on paid plans.
- Browse AI is quicker to learn and better for watching a few sites for changes. The free plan gives 50 credits a month across 2 websites.
- Octoparse has more control over pagination and complex pages, and a free plan with 10 tasks and local runs only.
- Both break the same way: when a site redesigns, someone has to retrain the robot or fix the task. Budget for that time every month, per site.
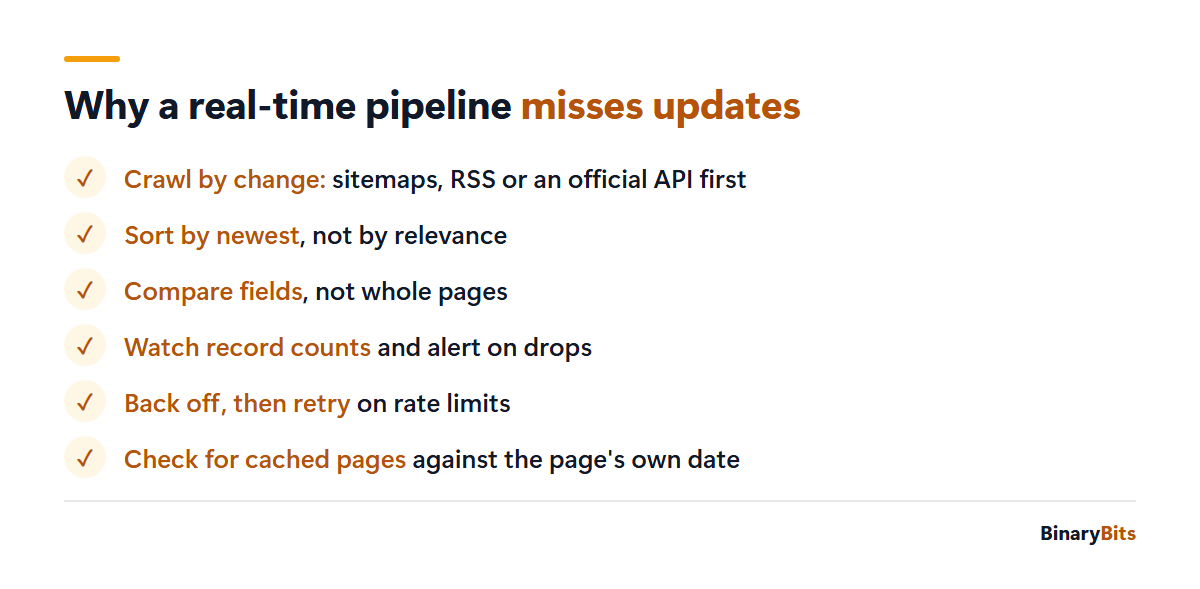
Why does my real-time scraping pipeline keep missing updates?
Usually because it's checking the wrong way, not because the tool is slow. The fixes below come from the pipelines we run; our job-data platform, for example, runs 15,000+ scrapers delivering 50,000+ fresh listings a day, and every one of these rules is in it.
- Crawl by change, not by schedule. Read sitemaps and their last-modified dates, RSS feeds or an official API before re-crawling whole sites.
- Sort by newest. Paging through a list sorted by relevance misses new items that land on page 30.
- Compare fields, not pages. Diff the price or the status, not the whole HTML, or ads and timestamps trigger false updates.
- Watch record counts. Alert when a source returns zero or far fewer rows than yesterday.
- Back off, then retry. Hitting rate limits returns errors that look like "no change". Slow down and retry later.
- Check for cached pages. Some sites serve stale copies to repeat visitors; compare against a page's own "updated" date.
When do web scraping tools stop being enough?
Tools stop being enough when the hard part is no longer fetching pages but everything around it. Watch for these signs:
- You scrape dozens of sites, each with its own quirks, and fixes pile up weekly.
- The data has to be matched across sources, cleaned and deduplicated before anyone can use it.
- It feeds something that breaks if it's late or wrong: pricing, a product, a client report.
- You need an audit trail of what was collected, when and from where.
What if our scraping project has eaten six months of engineering time?
That search shows up in our data, and it usually isn't a tool problem. Six months in, the scrapers mostly work; what's missing is monitoring, validation and someone who owns them. Switching tools rarely fixes that. You have three honest options:
| Option | Pick it when | What you still own |
|---|---|---|
| Move to a scraping API | Blocking and browsers are the main pain | Parsers, schedules, data checks |
| Build a proper pipeline | The data is part of your product | The code and the data; a team maintains it |
| Buy the data | You only need the output, not the system | Nothing technical |
If you only want the data, a delivered feed is often cheaper than any tool, and our sister company TheDataHQ explains when to run the scraper and when to buy the feed. If the data is part of your product, that's a system worth building properly, with its own backend and APIs.
Scrapers that work until they don't? We design and build scraping pipelines with monitoring, validation and clean delivery. See how we build web scraping platforms →
How do you choose the right web scraping tool?
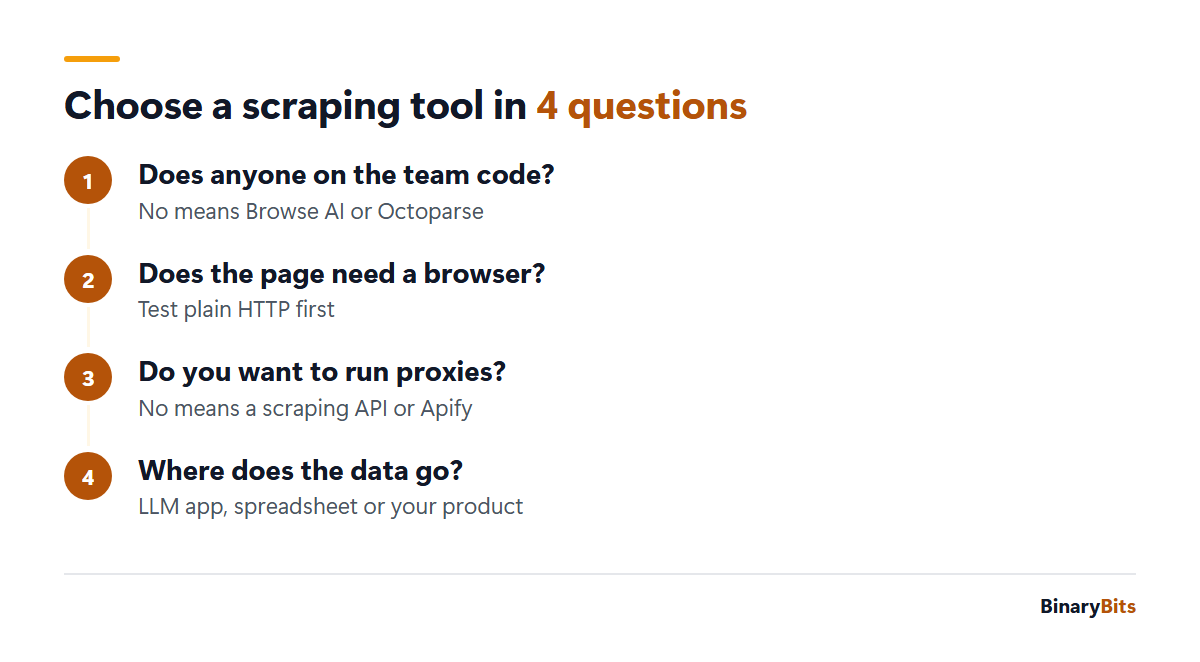
Answer four questions in order, and the shortlist picks itself.
- Does anyone on the team code? No: Browse AI or Octoparse. Yes: keep going.
- Does the page need a browser? Test with a plain HTTP request first. Only JavaScript-heavy pages need Playwright or a rendering API.
- Do you want to run proxies and servers? No: a scraping API or Apify. Yes: Scrapy or Crawlee.
- Where does the data go? An LLM app: Firecrawl or ScrapeGraphAI. A spreadsheet: any no-code tool. Your product: plan for monitoring and validation from day one.
One honest limit on this list: we test tools on the sites our projects need, not on yours. Every vendor above has a free tier or free credits, so run your own 50 hardest pages through two of them before you commit. For more on scraping product and price data, see web scraping for e-commerce.
Need a scraping pipeline your team doesn't have to babysit?
We've been building software for 10+ years, across 200+ projects in 10+ countries, and scraping pipelines are a big part of that. Tell us what you're collecting and where it needs to go, and we'll tell you honestly whether a tool will do. No pitch, just a conversation.
Frequently asked questions
Which scraping API requires the least maintenance over time?
AI extraction APIs such as Firecrawl and ScrapeGraphAI need the least upkeep, because they read pages with a language model instead of fixed selectors, so a layout change doesn't break them. Standard scraping APIs like ScrapingBee, ScraperAPI and Zyte API handle proxies and rendering but leave you maintaining parsers. With any of them, add checks that alert you when fields come back empty.
What are the best AI web scraping tools in 2026?
Firecrawl is the strongest pick for LLM and RAG apps, because it returns clean markdown or JSON from $19 a month. ScrapeGraphAI suits teams that want to describe fields in plain English, from $20 a month or free as an open-source library. Browse AI is the AI-assisted option for non-developers. Validate their output: models occasionally fill a field with the wrong value.
Which SaaS web scraping providers have the best Puppeteer integration?
Apify is the most direct option: it runs your own Puppeteer or Playwright code in its cloud, and its open-source Crawlee library includes a Puppeteer crawler. If you'd rather not host a browser at all, ScrapingBee can run scripted clicks and scrolls inside its own browser through the API. Test both with your hardest page before choosing.
How do I choose the right tool for automated web scraping?
Start with who will run it. Non-developers should pick Browse AI or Octoparse. Developers should test whether the page needs a browser at all, then decide whether to run their own proxies with Scrapy or Crawlee, or pay a scraping API to do it. If the data feeds an LLM, use Firecrawl. If it feeds your product, plan monitoring from day one.
What's a good ScrapingBee alternative for multi-step browser automations?
For flows with logins, clicks, forms and several pages in a row, Apify running a Playwright or Puppeteer script is the most flexible choice, since you write the steps in code and Apify hosts the browser. Browse AI records multi-step robots without code. For anything that runs every day and matters to your business, a custom Playwright job with its own monitoring is the most dependable.
Are there free web scraping tools?
Yes. Scrapy, Crawlee, Playwright and Puppeteer are free and open source; you only pay for servers and proxies. Most paid tools also have free tiers: Firecrawl, ScrapingBee, ScraperAPI and Scrapfly give 1,000 free credits, Octoparse offers 10 tasks on your own computer, and Visualping watches 5 pages hourly for free. Free tiers are for testing, not production volume.
Is web scraping legal in the US?
Collecting publicly available data is generally lawful in the US, but it depends on what you collect and how. Respect a site's terms and robots.txt, keep to reasonable request rates, don't collect data behind a login, and take extra care with personal data, which privacy laws such as California's CCPA cover. This is general information, not legal advice; ask a lawyer about your specific case.